Table of Contents
- Introduction
- Understanding Model Tokenization
- The Cost Structure
- Comparing Model Tiers
- Rate Limits and Throughput
- How to Monitor Usage
- Optimizing Costs for Production
- Managing API Authentication
- Handling API Errors
- Integration Best Practices
- Scaling Your Implementation
- Common Pitfalls
- Final Thoughts
Introduction
Choosing the right large language model for your business requires a deep dive into the underlying economics of the service. As developers and architects, we often prioritize performance, but the long-term sustainability of an AI product depends heavily on predictable expenses.
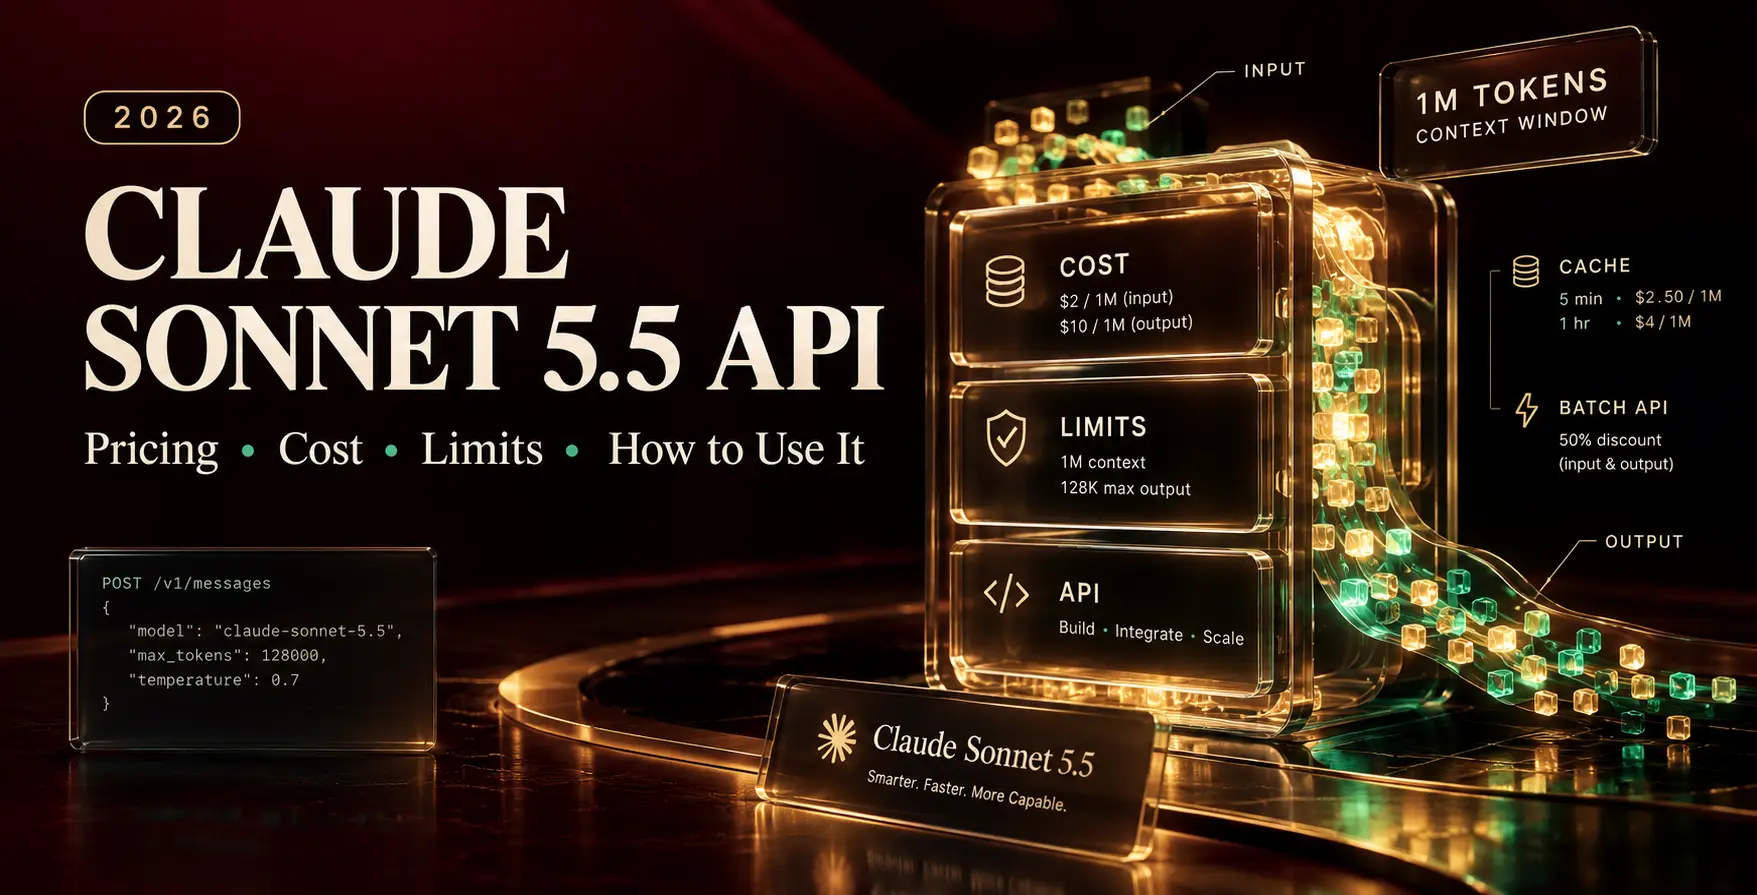
The Claude Sonnet 5.5 API pricing model provides a transparent way to scale your applications without unexpected surges. Understanding how these costs translate to your specific use case is essential for effective budget management.
Understanding Model Tokenization
Before calculating your monthly output, you must understand how tokens interact with the pricing model. Every request sent to the API is broken down into tokens, which represent snippets of text or characters.
Input tokens are processed differently than output tokens. Knowing this distinction is the first step toward accurate cost estimation for your specific workload.
- Input tokens cover your prompts
- Output tokens include the generated response
- Context window size impacts token memory
- Tokenizer efficiency varies by language
The Cost Structure
When you evaluate the Claude Sonnet 5.5 cost, you should look at the price per million tokens. Anthropic standardizes this across their platform to ensure fairness for developers of all sizes.
Predictability is a core component of the current Anthropic API pricing strategy. You are billed based on the total volume of text processed, meaning you only pay for what you actually use during production cycles.
| Usage Type |
Pricing Model |
| Input Cost |
Per 1M Tokens |
| Output Cost |
Per 1M Tokens |
| Cache Writes |
Per 1M Tokens |
| Cache Reads |
Per 1M Tokens |
Comparing Model Tiers
While Sonnet 5.5 is optimized for balance, you might consider other models depending on your specific requirements. Each model tier serves a distinct purpose in the development lifecycle.
Comparing these tiers helps you decide when to use a high-reasoning model versus a faster, more cost-effective alternative. Selecting the right tool for the job is a hallmark of senior engineering.
- Haiku for high-speed, low-cost tasks
- Sonnet for balanced reasoning and speed
- Opus for complex, high-reasoning requirements
Rate Limits and Throughput
Beyond the raw cost, you need to navigate the operational constraints of the service. Rate limits are designed to protect the stability of the infrastructure for all users.
Most enterprise accounts start with baseline limits that can be increased over time. Monitoring these limits is crucial to ensure your application remains responsive during peak traffic hours.
- Requests per minute
- Tokens per minute
- Concurrent request limits
- Burst capacity allocation
- Global account quotas
How to Monitor Usage
Effective management requires visibility into your consumption patterns. Using the dashboard provided by the developer console allows you to track spending in near real-time.
You should set up proactive alerts to notify your team when costs approach predefined thresholds. This level of oversight is a standard practice in modern engineering teams focusing on cloud cost optimization.
Optimizing Costs for Production
Prompt Engineering Techniques
You can significantly lower your expenses by refining your prompts to be more concise. Eliminating redundant instructions reduces the total input token count per call.
- Use structured system instructions
- Provide few-shot examples sparingly
- Summarize long documents before input
- Remove unnecessary conversational filler
Optimizing your prompt structure is an easy win for any developer looking to improve efficiency. Smaller prompts directly lead to lower monthly bills.
Caching Strategies
Leveraging prompt caching can drastically reduce the cost of repeating similar context. By reusing parts of your prompt, you avoid paying for full input re-processing.
- Cache static system instructions
- Reuse large reference documents
- Implement TTL-based cache invalidation
- Monitor cache hit rates daily
Caching is one of the most effective ways to lower your operational expenses. It also happens to improve latency, providing a better experience for your end users.
Managing API Authentication
Security should never be an afterthought when building production applications. Using environment variables to store your API keys keeps credentials out of your source code repository.
Rotate your keys frequently to mitigate the risk of unauthorized access. A robust security posture ensures that your infrastructure remains resilient and safe from external threats.
Handling API Errors
Distributed systems are inherently prone to intermittent failures. You must implement exponential backoff strategies to handle rate limits or network issues gracefully.
Proper error handling prevents your application from crashing during periods of high load. It also provides a better user experience by allowing the system to recover automatically from minor blips.
Integration Best Practices
Integration should be handled via a modular architecture to allow for model swapping. Designing your services to be agnostic of the specific LLM enables you to pivot quickly if requirements change.
Maintaining a clean separation between your business logic and the API layer is vital. This approach simplifies testing and makes your codebase much easier to maintain over time.
Scaling Your Implementation
As your user base grows, you will need to scale your infrastructure accordingly. Asynchronous processing is often the best way to handle long-running model queries without blocking your main threads.
Queueing requests and processing them in the background ensures that your system remains responsive. This architecture is standard when dealing with high-throughput AI services.
Common Pitfalls
Many developers fail to account for the impact of long conversation histories. As a chat session grows, the input token count increases, leading to higher costs per turn.
Implementing sliding window memory or summarization can mitigate these hidden costs. Always be mindful of how much context you are passing back to the model in each request.
Final Thoughts
Navigating the Claude Sonnet 5.5 API pricing landscape requires a mix of financial planning and technical discipline. By monitoring your usage, implementing caching, and optimizing your prompts, you can build powerful AI applications that remain cost-effective at scale.
Focus on building a robust architecture that treats AI services as a variable cost component. With the right strategies, you can deliver high-quality intelligence to your users while maintaining a healthy budget.


 In collaboration with