Table of Contents
- Introduction
- Understanding the Cache Stampede
- Why the Thundering Herd Problem Occurs
- The Impact on Database Performance
- Detection and Monitoring
- Locking Mechanisms for Protection
- Probabilistic Early Recomputation
- Graceful Degradation Patterns
- Optimizing Cache Expiration Policies
- Strategies for Hot Key Management
- Testing for Cache Resilience
- Best Practices for High-Traffic Apps
- Conclusion
Introduction
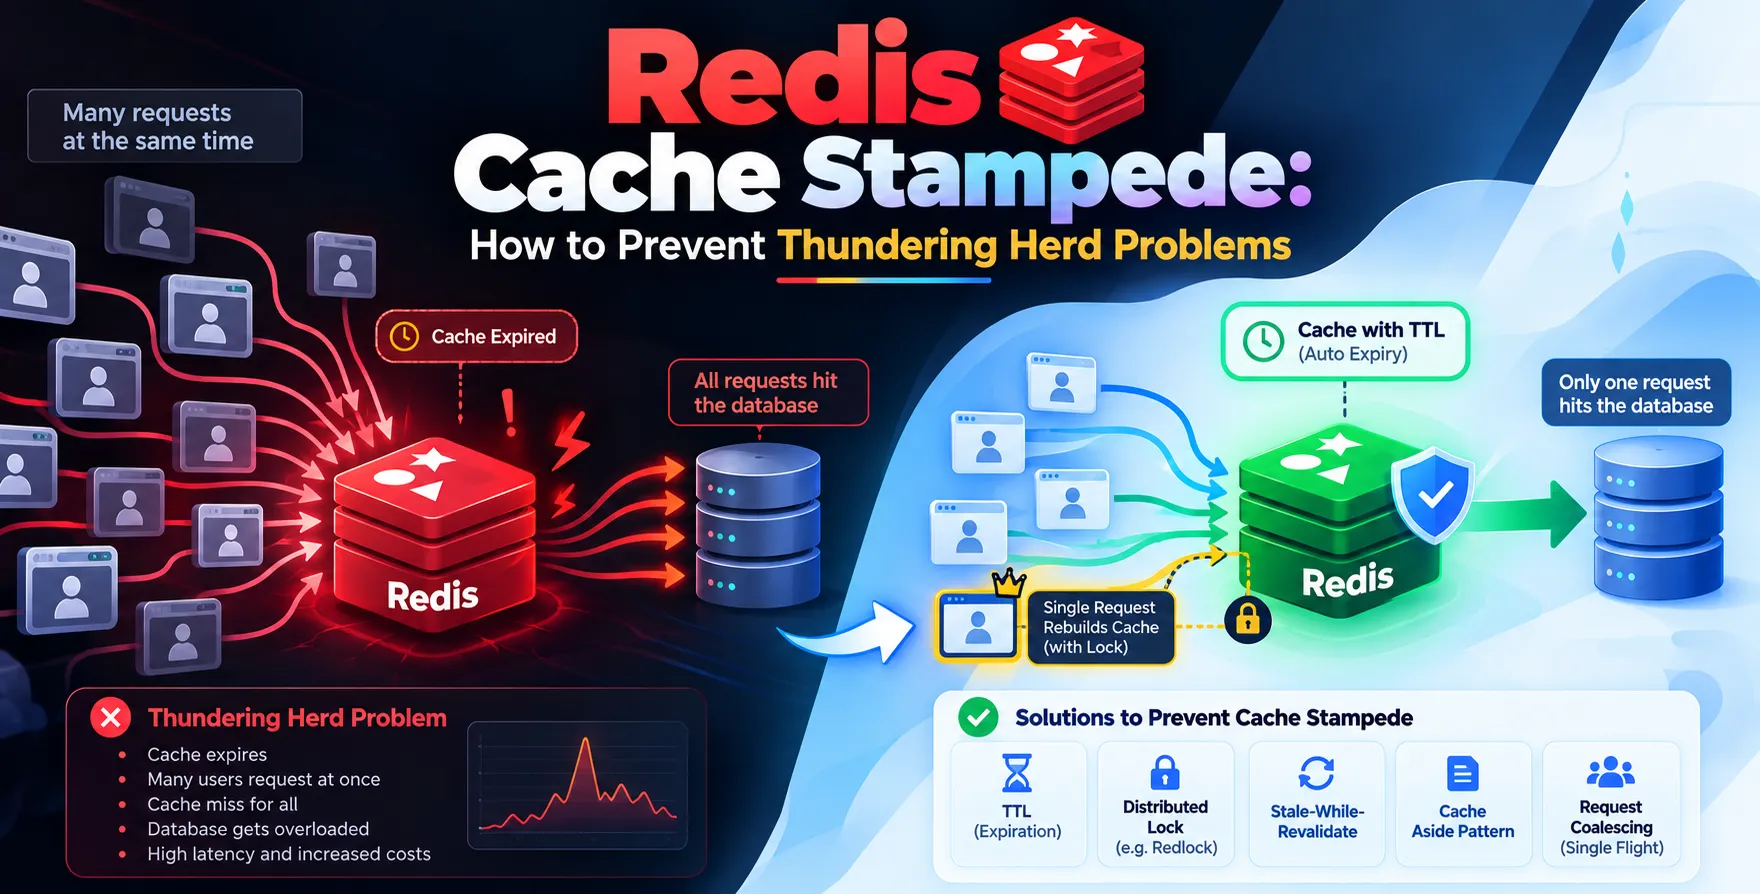
In high-performance systems, caching is often the first line of defense against database overload. However, a common failure mode known as the Redis cache stampede can quickly turn a performance booster into a bottleneck. When an important cache key expires, the sudden surge in concurrent requests can overwhelm your backend services.
Addressing the thundering herd problem requires a combination of architectural patterns and smart invalidation strategies. By implementing proactive cache stampede prevention, developers can ensure their applications remain responsive even during heavy traffic spikes. This guide explores how to identify these issues and implement robust architectural safeguards.
Understanding the Cache Stampede
A cache stampede occurs when multiple concurrent processes simultaneously identify that a required data item is missing from the cache. Because the data is absent, every process attempts to fetch the missing value from the underlying database at the exact same moment. This creates an immediate, massive spike in read operations directed at your primary data store.
Instead of a single database query, you suddenly face hundreds or thousands of identical queries. This surge often leads to increased latency, connection pool exhaustion, and potential downtime. Effectively managing the lifecycle of your cached items is vital for system reliability.
- Simultaneous cache misses across threads
- Redundant database queries for the same key
- Increased latency for end users
- Resource exhaustion in the backend
Why the Thundering Herd Problem Occurs
The core issue is a race condition triggered by expiration. When a high-traffic key hits its Time-To-Live (TTL), the very next request sees a miss and initiates a refresh. If the refresh process takes longer than a few milliseconds, subsequent requests also see a miss and start their own refresh threads.
This behavior is common in systems without coordination between workers. As more requests pile up, the database struggles to keep pace, further slowing the refresh process. This creates a feedback loop where the cache remains empty while the database is hammered by redundant work.
- Short TTL values on hot keys
- High concurrency in web applications
- Slow execution of heavy database queries
- Lack of distributed locking mechanisms
The Impact on Database Performance
The thundering herd problem is rarely confined to the caching layer itself. As the database becomes saturated with duplicate requests, other parts of the application begin to suffer. Even unrelated queries may timeout while waiting for an available connection or CPU time.
This cascading effect can degrade your entire infrastructure. If your application relies on monolithic vs microservices architecture, the impact may ripple across multiple service boundaries. Maintaining database health is essential, especially when dealing with complex read-heavy operations.
Resource Starvation
When the database is busy handling redundant queries, legitimate traffic is queued or dropped. This creates a significant drag on overall system throughput.
- Increased connection wait times
- High CPU utilization on database nodes
- Increased latency for all users
- Risk of cascading system failure
Operational Costs
Frequent stampedes force you to over-provision hardware just to survive transient load spikes. This leads to wasted budget and inefficient resource utilization that could be avoided with better code.
- Higher infrastructure costs
- Need for larger database instances
- Increased maintenance overhead
- Unnecessary scaling events
Detection and Monitoring
Detecting a cache stampede in progress requires granular observability into your request patterns. You should track cache miss rates correlated with database load spikes. If you see a sudden jump in database queries immediately following a cache expiration, you are likely facing a stampede.
Advanced monitoring tools can help visualize these patterns over time. Look for correlations between high-frequency keys and database performance metrics. Establishing a baseline for normal cache behavior makes it easier to spot these anomalies as they happen.
Locking Mechanisms for Protection
Using distributed locks is a classic approach to prevent multiple processes from performing the same task. By forcing only one process to refresh the cache while others wait or return stale data, you effectively serialize the update.
Redis itself provides powerful primitives for implementing distributed locks. Ensure your lock timeout is short enough to prevent deadlocks if a process crashes during the refresh. This simple pattern is highly effective for critical, low-frequency data.
- Acquire a lock before query execution
- Refresh the cache value
- Release the lock promptly
- Return cached data to waiting requests
Probabilistic Early Recomputation
Rather than waiting for a hard expiration, you can implement probabilistic early recomputation. This strategy involves calculating the probability of recomputing a key before it actually expires based on how much time is left. This approach gradually increases the likelihood of a refresh as the expiration time approaches.
This method smooths out the load by distributing recomputation attempts over time. It is particularly useful for very high-traffic keys where even a small delay in cache refresh is unacceptable. It turns a sharp cliff into a gentle slope of activity.
Graceful Degradation Patterns
When the database is under extreme load, sometimes the best strategy is to return slightly stale data. Allowing your application to serve an expired cache entry while a background job fetches the fresh value is a powerful technique. This ensures that the user experience remains fast, even if the data is a few seconds old.
This approach requires careful design of your cache client. Most modern libraries support returning stale values if the underlying fetch fails or takes too long. By prioritizing availability over absolute consistency, you can maintain system stability during unexpected traffic surges.
Optimizing Cache Expiration Policies
Not all keys should have identical expiration times. Implementing jitter—adding a random amount of time to your TTL—can prevent many keys from expiring at the exact same moment. This technique effectively spreads out the load and reduces the probability of a synchronized stampede.
Another strategy involves separating your cache keys into different tiers. Highly volatile data should have shorter TTLs, while stable data can persist longer. This granular control over your cache lifecycle is a fundamental part of building scalable software.
- Add random jitter to expiration times
- Tier your cache by data volatility
- Set longer TTLs for static assets
- Monitor cache hit-to-miss ratios
Strategies for Hot Key Management
Hot keys are the primary targets for cache stampedes. Identifying these keys early allows you to apply specific protections, such as pre-warming or constant background refreshes. If you know a key will be accessed millions of times, keep it hot in your memory.
Using a background job system to periodically update these keys ensures the cache is never truly empty. This shifts the burden of database interaction away from the request-response cycle entirely. It is a proactive way to maintain high availability.
Testing for Cache Resilience
You cannot effectively prevent stampedes without testing your system under simulated high-load conditions. Use load testing tools to artificially induce cache misses and observe how your application handles the concurrent database requests. This validates your locking and recomputation logic before it hits production.
Simulate both normal traffic and worst-case scenarios where large groups of keys expire simultaneously. Understanding your system's breaking point is essential for fine-tuning your configuration. Regular testing ensures your safeguards remain effective as your application evolves.
Best Practices for High-Traffic Apps
Building a robust caching layer is an ongoing process of refinement. Always prioritize simplicity in your locking logic to avoid introducing new bugs. Monitor your cache performance as closely as your database metrics to maintain a balanced system architecture.
Stay informed about new features in your caching engine that might simplify these patterns. Modern Redis versions offer various tools that can streamline cache management. Investing in these practices early prevents technical debt and keeps your system performing well at scale.
- Keep locking logic simple and fast
- Monitor cache hit rates continuously
- Use jitter to stagger expirations
- Implement stale data fallback mechanisms
- Test under simulated load frequently
Conclusion
Preventing cache stampedes is a critical skill for any developer working with high-scale systems. By understanding the mechanics of the thundering herd, you can apply the right patterns to protect your database. Whether through distributed locking or probabilistic recomputation, the goal is always to balance consistency with performance.
Consistent monitoring and rigorous testing are the best ways to ensure your cache remains a reliable asset. By proactively managing how your application handles cache misses, you ensure stability for your users and peace of mind for your team. Build with these patterns in mind to create truly resilient applications.


 In collaboration with