Table of Contents
- Understanding Django Bulk Operations
- When to Use bulk_create
- The Impact of Signals on Bulk Operations
- Transaction Trade-offs in Django
- Managing Performance with batch_size
- Handling Complex Database Updates
- Comparing bulk_create and bulk_update
- Database Maintenance and Performance
- When Not to Use Bulk Methods
- Scaling Data Processing Workflows
- Best Practices for High-Traffic Apps
- Optimizing Query Performance
- Common Pitfalls to Avoid
- Conclusion
Understanding Django Bulk Operations
Django provides powerful tools for database interaction that go beyond simple object-level saving. When you need to process large datasets, using standard ORM methods like .save() inside a loop can cripple your database performance.
This is where Django bulk operations come into play as a superior alternative. These methods allow you to minimize round-trips to the database by bundling multiple operations into a single query.
- Reduces network latency
- Minimizes transaction overhead
- Decreases CPU load on the database
- Improves overall application throughput
When to Use bulk_create
The bulk_create method is your go-to tool for inserting large volumes of new records. Instead of executing hundreds of individual INSERT statements, it constructs a single command to push all data at once.
This approach is significantly faster for data ingestion tasks or migrating records from external sources. It bypasses the overhead of initializing individual model instances for every row.
- Efficient for bulk data loading
- Drastically lowers insertion time
- Requires careful handling of model constraints
The Impact of Signals on Bulk Operations
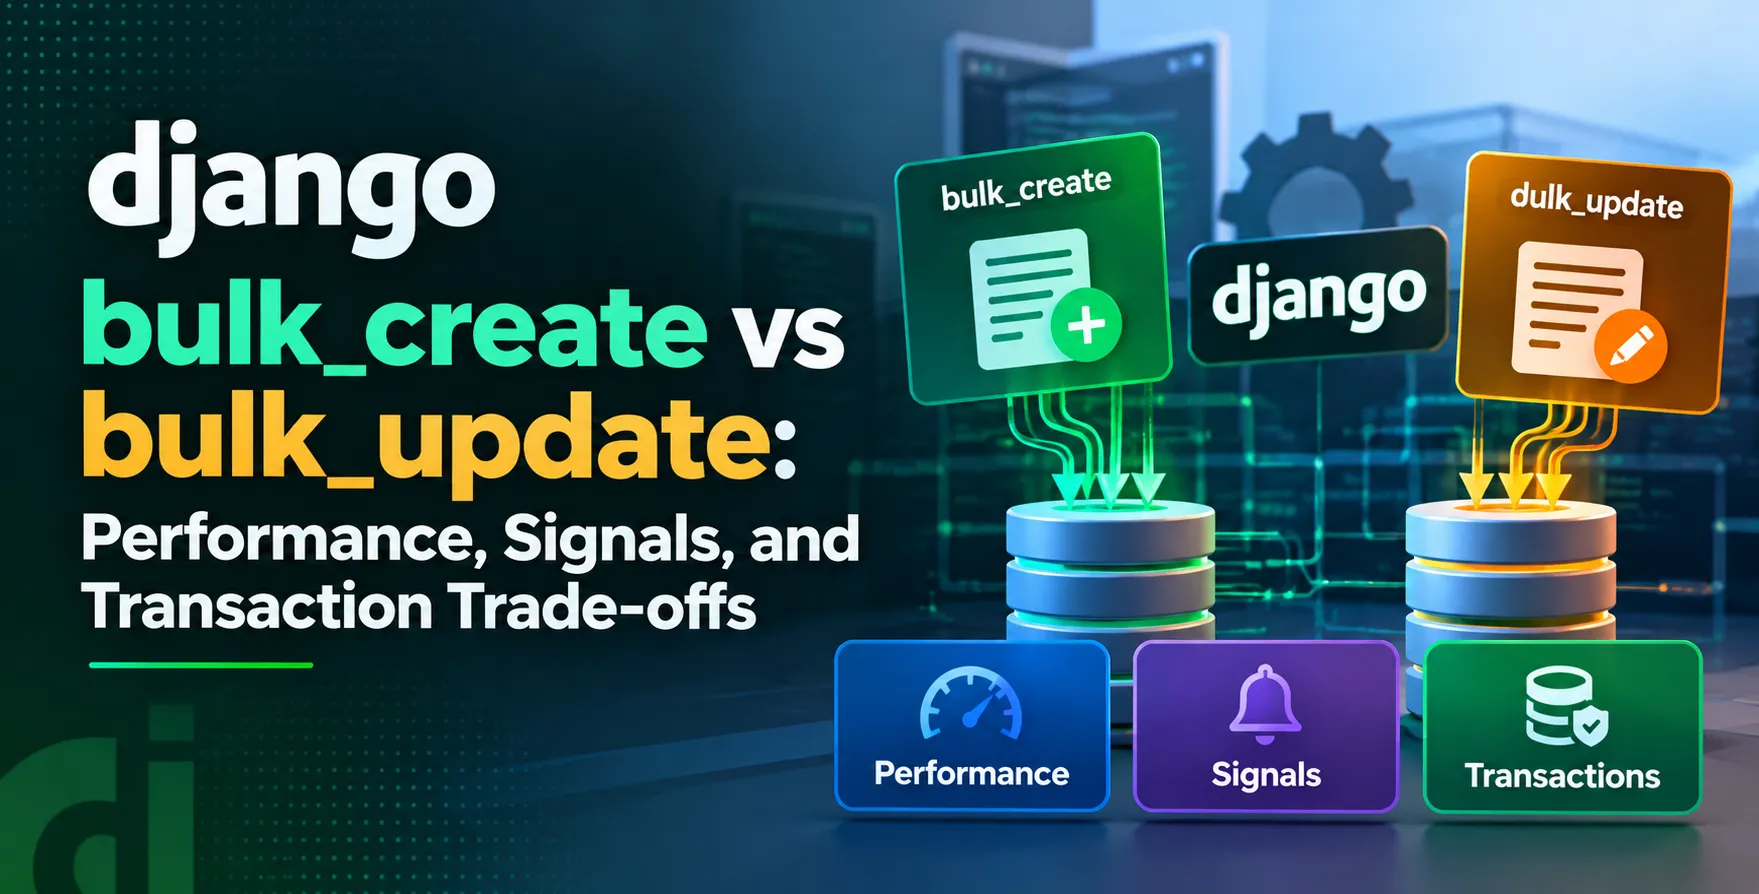
A critical point many developers miss is that Django bulk_create signals are not sent during these operations. If your application relies on post_save or pre_save hooks to trigger side effects like clearing caches or sending notifications, these will be skipped entirely.
This design choice is intentional to maintain high performance. By avoiding individual instance initialization, the ORM saves significant processing time at the cost of bypassing the standard signal lifecycle.
Developers must handle these side effects manually after the bulk operation completes. Failing to account for this can lead to data inconsistency across your application state.
- pre_save hooks are ignored
- post_save hooks are ignored
- m2m_changed is not triggered
- Logic must be handled explicitly
Transaction Trade-offs in Django
Using bulk methods requires a thoughtful approach to transaction management. Wrapping your operations in an atomic block ensures that if one part of the batch fails, the entire operation rolls back to keep your database in a consistent state.
Without explicit transaction control, you risk partial failures where some rows are inserted while others are not. This is particularly dangerous in complex data pipelines where atomicity is a business requirement.
- Guarantees data integrity
- Prevents partial database updates
- Provides safety for batch jobs
- Essential for complex relational data
Managing Performance with batch_size
When working with massive datasets, sending everything in one giant query might hit your database server's limit. You should utilize the Django bulk_update batch_size argument to chunk your data into manageable pieces.
Setting an appropriate batch size prevents memory exhaustion and avoids exceeding the maximum number of parameters allowed by your database backend. It strikes a balance between total execution time and resource utilization.
- Prevents memory overflow errors
- Optimizes database connection usage
- Allows for granular progress tracking
- Reduces risk of query timeouts
Configuring Batch Sizes
Selecting the right size depends on your row width and database capacity. A size between 500 and 2000 is typically a safe starting point for most web applications.
- Test with different sizes
- Monitor database resource consumption
- Adjust based on row complexity
Always test your specific workload to find the sweet spot for your infrastructure.
Handling Complex Database Updates
While bulk_create is for new rows, bulk_update is designed for modifying existing records efficiently. It generates a single SQL UPDATE statement or a series of optimized updates to change multiple fields across different instances.
This method is highly effective for updating statuses or syncing external data changes. Like its creation counterpart, it does not trigger model save methods or signals, which makes it performant but potentially dangerous if you rely on auto-updated timestamps.
Comparing bulk_create and bulk_update
| Feature |
bulk_create |
bulk_update |
| Primary Purpose |
New record insertion |
Existing record modification |
| Signal Triggering |
None |
None |
| Return Value |
List of objects |
Number of rows updated |
| Performance Impact |
Very high gain |
High gain |
| Constraint Handling |
Database level |
Database level |
Database Maintenance and Performance
High-volume bulk operations can cause significant table bloat if not managed properly. Frequent deletions or updates can lead to fragmentation, requiring regular maintenance to keep your queries fast.
Implementing consistent PostgreSQL VACUUM best practices is essential for maintaining performance in environments where large batches are processed daily. Without this, your database will struggle to reuse dead tuples, leading to degraded performance over time.
When Not to Use Bulk Methods
There are scenarios where the traditional .save() method is actually better. If you have complex validation logic inside the model's clean() method or need to trigger critical signals, bulk operations are not the right choice.
Always prioritize code correctness over raw performance when the logic dictates individual processing. Sometimes, the business cost of a missing signal is far greater than the technical cost of a slower execution.
- When signals are mandatory
- For models with complex validation
- When working with very small sets
Scaling Data Processing Workflows
Scaling your background workers is often necessary when dealing with massive data imports. You might want to consider offloading these tasks to a dedicated worker queue to keep your web application responsive.
Using a task queue allows you to process batches asynchronously without blocking the user. This ensures that your main application remains performant even under heavy load.
- Use asynchronous task runners
- Parallelize batch processing tasks
- Monitor worker queue latency
- Implement error logging for batches
Best Practices for High-Traffic Apps
In high-traffic environments, connection pooling becomes critical to handle the surge of queries generated by bulk processes. Proper configuration ensures that your application doesn't exhaust the available database connections during peak times.
Combine this with efficient indexing strategies to ensure your bulk operations don't lock tables for longer than necessary. A well-indexed table will speed up both lookups and the internal logic used by bulk_update to identify rows.
- Use robust connection pooling
- Optimize column indexing
- Avoid long-running transactions
- Log batch operation performance
Optimizing Query Performance
Query optimization is an ongoing process. Regularly profiling your application helps identify bottlenecks before they impact your users. If you see slow performance during bulk operations, look at the generated SQL to ensure it matches your expectations.
Sometimes, a slight change in the batch size or the structure of your data can yield massive performance gains. Always aim to keep the database workload as predictable and lean as possible.
Common Pitfalls to Avoid
One common mistake is assuming that bulk methods are drop-in replacements for standard model saving. You must always check your code for dependencies on signals or hidden model logic.
Another pitfall is ignoring database constraints. Bulk methods will fail if they violate unique or foreign key constraints at the database level, and these errors can be harder to debug than standard model exceptions.
- Assuming signals will fire
- Ignoring database constraints
- Overloading the batch size
- Neglecting transaction atomicity
Conclusion
Mastering bulk methods in Django is essential for any developer working on high-performance applications. By understanding the performance characteristics and the trade-offs regarding signals and transactions, you can make informed decisions that keep your application fast and reliable.
Always test your implementation under load and monitor your database to ensure that these optimizations continue to serve your needs as your dataset grows. With careful planning, you can leverage these powerful tools to handle massive data operations with ease.


 In collaboration with