Table of Contents
- Understanding Web Caching Basics
- Why Redis for Caching?
- Key Redis Caching Strategies to Speed Up Web Applications
- Implementing Cache-Aside Pattern
- The Write-Through Caching Approach
- Write-Behind Caching Explained
- Handling Redis Cache Invalidation
- Common Pitfalls in Web Application Caching
- Choosing the Right Expiration Policy
- How Caching Impacts Overall System Latency
- Comparing Caching Architectures
- Best Practices for Production Environments
- Final Thoughts
Understanding Web Caching Basics
Modern users demand instant responses from every digital service they touch. When a database query takes too long, the user experience suffers, and conversion rates drop significantly.
Caching acts as a high-speed data buffer between your application and the underlying storage layer. By storing frequently accessed results in memory, you avoid repeated heavy computations or expensive disk operations.
Effective web application caching is not just about speed. It is about reducing the load on your primary databases and improving the overall stability of your infrastructure.
- Reduces database query frequency
- Lowers server-side processing overhead
- Provides near-instant data retrieval
- Increases system scalability
Why Redis for Caching?
Redis stands out as the industry standard for in-memory data structures. Its architecture allows for sub-millisecond response times, making it ideal for high-traffic environments.
Unlike traditional relational databases that rely on disk storage, Redis keeps the entire dataset in RAM. This design choice provides the extreme throughput necessary for modern web scale.
Using Redis in your tech stack allows you to handle complex data types beyond simple strings. You can store lists, hashes, sets, and sorted sets to accommodate diverse application requirements.
- Extremely low latency
- Supports complex data structures
- Built-in persistence options
- High availability and clustering
Key Redis Caching Strategies to Speed Up Web Applications
Choosing the right approach depends on your specific read-write ratio. Most systems benefit from a hybrid model that balances data freshness with speed.
Your choice of Redis caching strategies to speed up web applications should align with how often your underlying data changes. If your data is relatively static, simple patterns work fine.
However, dynamic platforms require more robust synchronization logic. You must carefully design your cache layer to prevent stale data from reaching the end user.
- Cache-aside pattern for general use
- Write-through for data consistency
- Write-behind for high-throughput logging
- Refresh-ahead to predict user requests
Implementing Cache-Aside Pattern
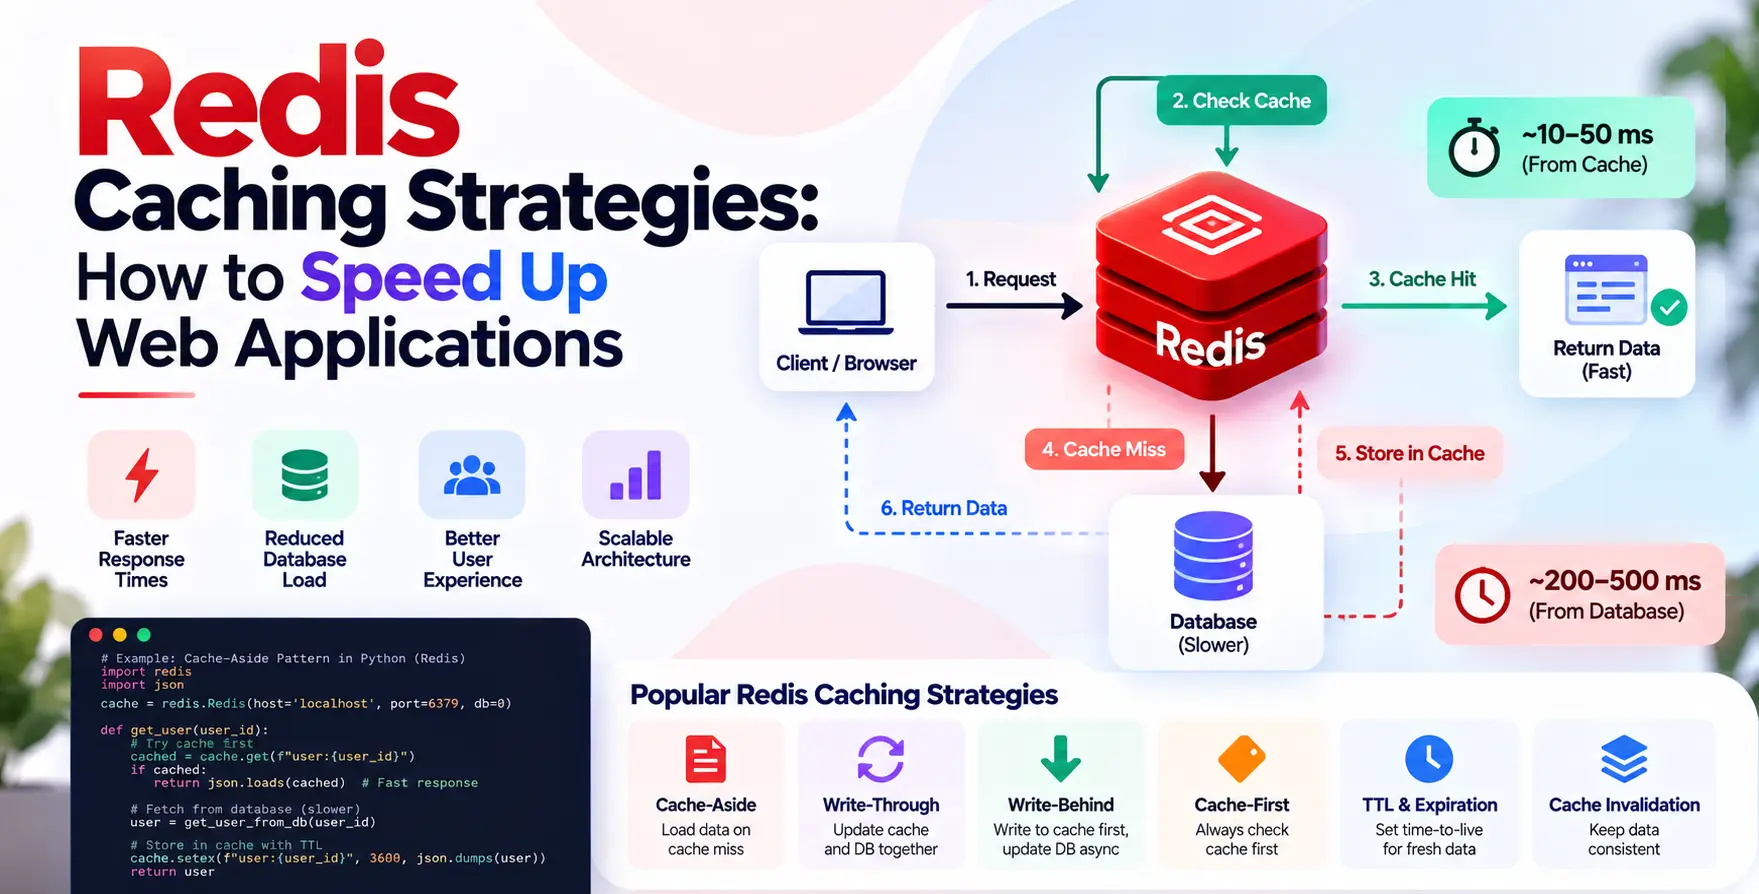
The cache-aside pattern is the most common approach for general-purpose applications. The application first attempts to read data from the cache.
If the data is not found, the system queries the database and populates the cache for future requests. This approach ensures that only requested data occupies your precious memory space.
This method is highly resilient because the application continues to function even if the Redis instance experiences a temporary failure. It essentially treats the cache as an optional optimization layer.
- Simple to implement in most codebases
- Provides high fault tolerance
- Only caches frequently accessed data
- Minimizes memory wastage
The Write-Through Caching Approach
Write-through caching ensures that your database and cache stay perfectly synchronized. Whenever the application updates data, it writes to the cache and the database simultaneously.
This guarantees that the next read operation will always find the most recent version in the cache. It is an excellent choice for financial applications where data integrity is paramount.
While this strategy provides strong consistency, it can introduce slight latency during write operations. You are effectively performing two distinct storage operations for every update event.
- Ensures data consistency
- Reduces cache misses
- Simplifies read logic
- Increases write latency slightly
Write-Behind Caching Explained
Write-behind caching, or write-back, prioritizes performance above all else. The application writes data to the cache immediately and updates the database asynchronously later.
This is extremely useful for high-volume scenarios like social media feeds or sensor logging. It allows the system to acknowledge a successful write operation in milliseconds.
You must consider the trade-off regarding data loss. If the cache fails before the background process updates the database, that information could be lost permanently.
- Maximizes write performance
- Reduces database contention
- Ideal for non-critical logs
- Requires robust background workers
Handling Redis Cache Invalidation
Managing the lifecycle of your cached items is the hardest part of distributed systems. Redis cache invalidation is essential to prevent users from seeing outdated or incorrect information.
You can use Time-To-Live (TTL) values to automatically expire entries after a set duration. This provides a safety net for data that changes predictably over time.
For more complex scenarios, you might need manual invalidation. This involves explicitly deleting or updating cache keys whenever the source of truth changes in your main database.
- Time-based expiration policies
- Manual key deletion events
- Pub/sub invalidation messaging
- Version-based cache tagging
Common Pitfalls in Web Application Caching
Caching is not a silver bullet and introduces its own set of technical challenges. One major issue is the cache stampede, where multiple requests attempt to rebuild a missing key simultaneously.
Another common mistake is caching sensitive user-specific data insecurely. Always ensure that private data is either encrypted or scoped correctly to prevent cross-user leakage.
You should also monitor your memory usage closely. When Redis runs out of memory, it starts evicting keys based on its policy, which can degrade performance unexpectedly.
- Cache stampede during high traffic
- Memory exhaustion and eviction
- Insecure data storage patterns
- Stale data serving issues
- Complexity in distributed synchronization
Comparing Caching Architectures
| Strategy |
Read Speed |
Write Speed |
Consistency |
| Cache-Aside |
Fast |
Fast |
Eventual |
| Write-Through |
Fast |
Moderate |
Strong |
| Write-Behind |
Fast |
Very Fast |
Eventual |
| Refresh-Ahead |
Instant |
Moderate |
Eventual |
Final Thoughts
Optimizing your application with Redis requires a deep understanding of your data access patterns. There is no one-size-fits-all solution for every architectural challenge you encounter.
Start by identifying your most expensive queries and applying a simple cache-aside strategy. Measure the performance gains before adding more complex layers like write-behind or manual invalidation.
Maintaining a high-performance system is an ongoing process of monitoring and adjustment. Keep your cache layers clean, your TTLs sensible, and your invalidation logic robust to ensure long-term success.


 In collaboration with