Table of Contents
- Introduction
- What is Idempotency?
- The Problem of Duplicate Requests
- Why Use Idempotency Keys?
- Designing the Header Strategy
- Storage Layer Considerations
- Handling Concurrent Requests
- Response Caching Logic
- Common Implementation Pitfalls
- Testing Your Idempotency Strategy
- Security Implications
- Integration with Existing Workflows
- Conclusion
Introduction
Building reliable distributed systems requires planning for the unexpected. Network timeouts and retries are inevitable in any modern cloud environment.
When a client sends a request that fails due to a network glitch, the natural response is to retry. Without proper handling, this can lead to duplicate payments, double records, or corrupted state.
What is Idempotency?
An operation is idempotent if performing it multiple times yields the same result as performing it once. In the context of web services, this is a cornerstone of robust API design.
GET, PUT, and DELETE methods are naturally idempotent by standard definitions. POST requests, however, create new resources and are inherently non-idempotent.
By introducing a mechanism to track intent, we can make non-idempotent operations safe for retries. This is the primary role of idempotency keys in modern systems.
The Problem of Duplicate Requests
Imagine a user clicking a checkout button twice because the page appeared to hang. If the backend processes both clicks, the user gets charged twice.
This scenario is common in mobile applications where connectivity is unstable. The client may send the request, lose signal, and send it again upon reconnection.
Without a way to recognize these requests as identical, the database will treat them as two distinct events. This creates a significant burden for support teams and ruins the user experience.
- Double charging customers
- Duplicate inventory deductions
- Inconsistent database states
- Increased server load
- Complex cleanup requirements
Why Use Idempotency Keys?
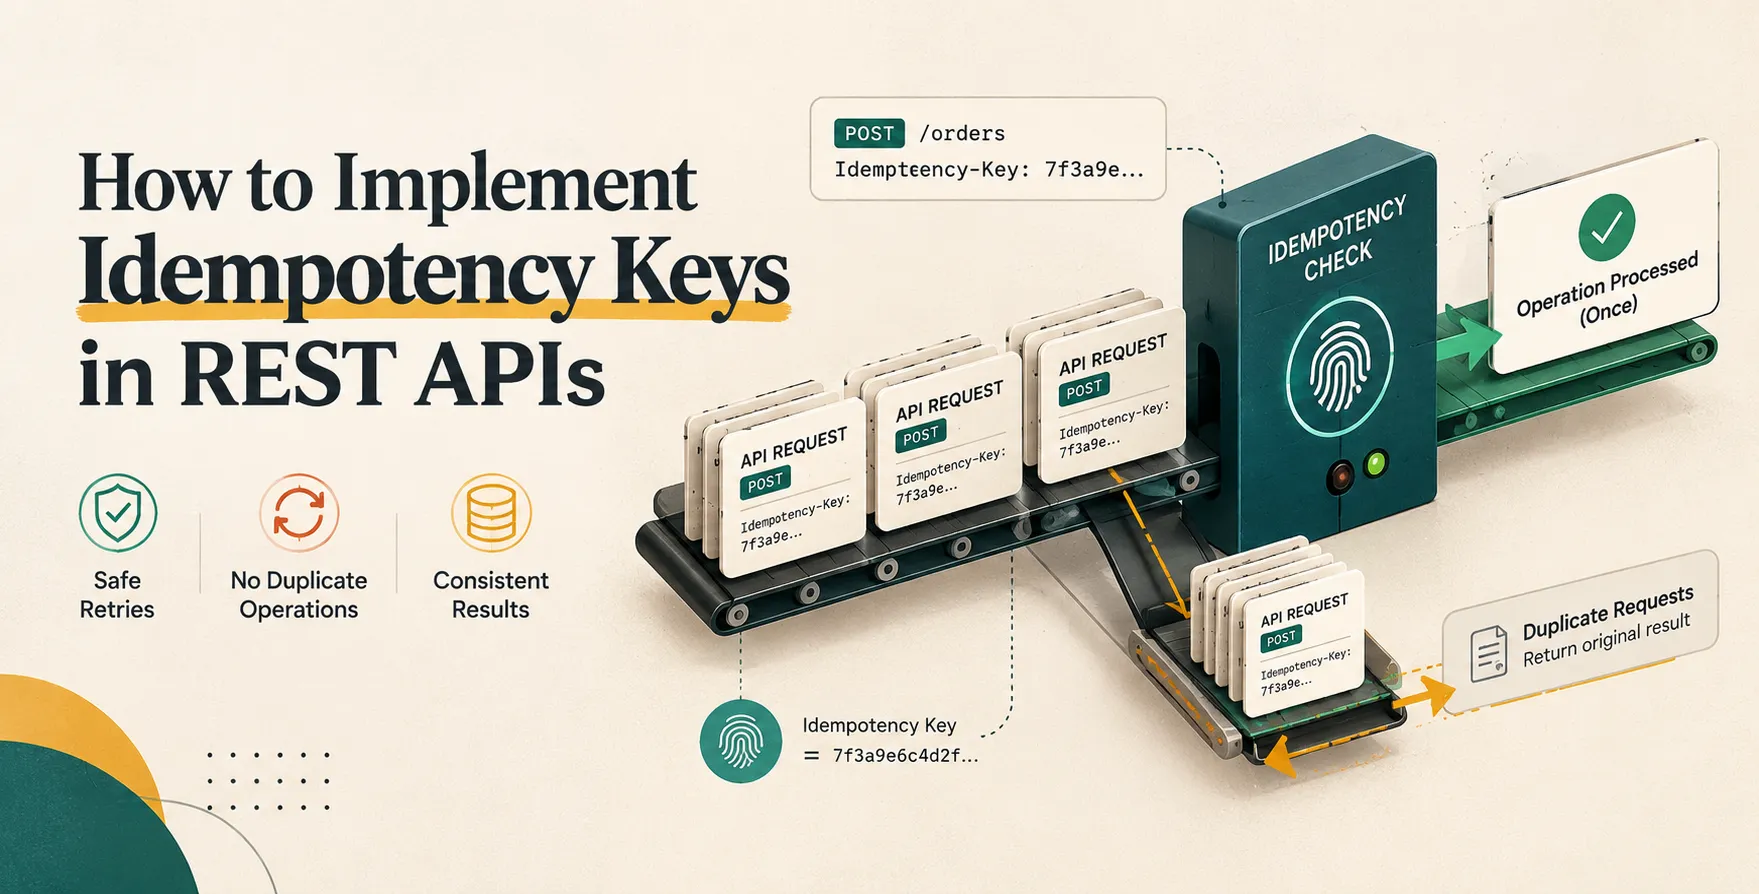
Idempotency keys provide a unique identifier for a specific intent. By requiring clients to send this key, the server can track whether a request has already been processed.
When a client sends a request with an idempotency key, the server checks its store for a match. If found, it returns the cached response from the original execution rather than running the logic again.
This pattern is essential for any API dealing with money, inventory, or state transitions. It transforms potentially dangerous retries into harmless, predictable events.
Designing the Header Strategy
Standardizing the Header
The most common approach is to use a specific HTTP header for the key. Standard practice involves using a custom header, such as Idempotency-Key or X-Idempotency-Key.
- Use a standard header name
- Expect a UUID v4 format
- Validate the key presence
- Enforce length constraints
- Reject malformed headers
This keeps the request body clean and strictly focused on business logic. It also makes your API easier to debug for client developers.
Client-Side Requirements
Clients must generate a unique UUID for every new business operation. They should store this key locally and reuse it if they decide to retry a failed request.
The server must treat the combination of the user's identity and the idempotency key as a unique fingerprint. Never rely on the client to guess or manage state beyond sending the key.
Storage Layer Considerations
You need a fast, temporary storage layer to track these keys. Redis is the industry standard for this purpose due to its low latency and built-in TTL support.
When a request hits your server, you first attempt to insert the key into Redis. If the key already exists, you know the request is a duplicate.
If the key does not exist, you proceed with the business logic. Once the operation succeeds, you save the result of the operation in the same store.
Handling Concurrent Requests
What happens if two identical requests arrive at the exact same millisecond? Race conditions can lead to both threads thinking they are the first to arrive.
You must use atomic operations to handle this scenario. A simple 'set if not exists' command in your cache layer prevents both threads from proceeding.
- Use atomic set commands
- Lock the record during processing
- Return a specific status code
- Avoid database deadlocks
- Maintain consistency across nodes
By locking the key immediately, you ensure that only one thread executes the logic. Other threads must wait or be told to retry later.
Response Caching Logic
Once a request is successfully processed, the server must store the response. This includes the HTTP status code, the response body, and any relevant headers.
If a repeat request arrives, the server retrieves the cached response and returns it immediately. This saves significant database and compute resources.
Ensure your TTL (Time To Live) for these keys is long enough to cover typical retry windows. Twenty-four hours is usually sufficient for most use cases.
Common Implementation Pitfalls
Many developers fail to validate the request payload along with the key. An attacker could potentially reuse a key with a different body to trick the system.
Always verify that the request body matches the signature of the original request. If the body changes, you should reject the request with a 400 Bad Request error.
- Ignoring payload validation
- Setting TTL too short
- Failing on concurrent requests
- Lack of persistent logging
- Returning incorrect status codes
Another mistake is failing to handle partial failures. If your process involves multiple database tables, ensure you use transactions to maintain atomic consistency.
Testing Your Idempotency Strategy
Simulating Network Failures
You must test how your API behaves when connections drop midway. Use tools to simulate latency and packet loss between your client and server.
- Create intentional network drops
- Test with concurrent requests
- Verify consistent response data
- Check database integrity
- Monitor cache usage metrics
This ensures your logic handles edge cases before you deploy to production. Automated testing is vital for maintaining confidence in your system's reliability.
Security Implications
Idempotency keys should not be used as a security mechanism. They are meant for reliability, not for authenticating users or preventing unauthorized access.
Always combine your idempotency strategy with robust authentication methods. Ensure that a key generated by one user cannot be used by another to trigger a duplicate process.
Treat the idempotency store as sensitive data. Regularly purge old keys to keep your storage footprint manageable and secure.
Integration with Existing Workflows
Implementing this pattern often requires a shift in how you write your business logic. You must separate the 'intent' from the 'execution'.
Consider using middleware to handle the idempotency logic. This allows you to keep your business services clean and focused on their primary domain responsibilities.
By centralizing this logic, you can easily apply it to all endpoints that perform state-changing operations. It simplifies maintenance and ensures consistent behavior across your entire API surface.
Conclusion
Implementing idempotency keys is a necessary step for any production-grade REST API. It protects your system from the inherent instability of network communications.
By carefully designing your header strategy, storage layer, and concurrency handling, you can ensure your system remains consistent. The effort you put into this pattern will pay dividends in user trust and operational stability.
Start small by applying this to your most critical write operations. Once you see the benefits, you can expand it across your entire platform.
- Improves API reliability
- Protects data integrity
- Enhances user experience
- Reduces server load
- Simplifies retry logic


 In collaboration with